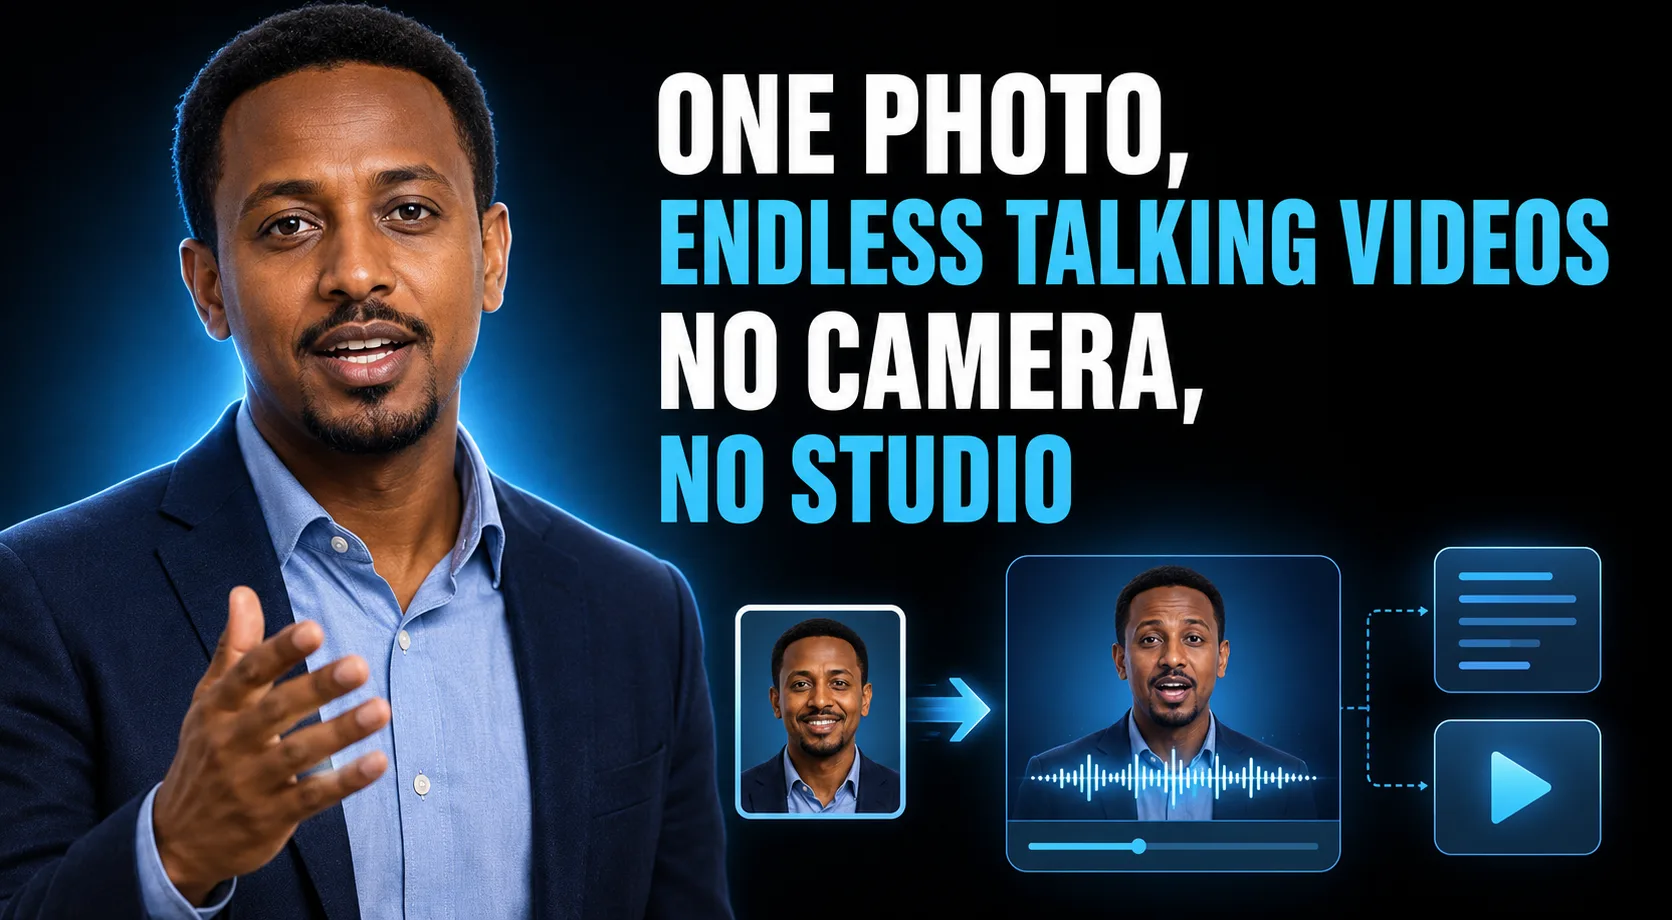
D-ID generates talking-avatar videos from a photo and a script, positioned for training, sales, and customer-facing content where a presenter is needed but filming one isn't practical or scalable.
What it does
A closer look at D-ID's talking avatar generation
D-ID takes a static image (a photo or generated avatar) and a text or audio script and produces a video of that "person" speaking, using lip-sync and facial animation matched to the audio. It's marketed toward marketing, sales enablement, training/e-learning, and customer experience use cases where a consistent on-camera presenter is needed repeatedly without booking studio time.
The practical use case is a company producing recurring training content, product explainer videos, or personalized sales outreach video at a volume where filming a real presenter for every version isn't feasible — one photo and script in, one video out.
It competes directly with Synthesia and HeyGen in the AI avatar category, both of which are also candidates for this kind of tool and worth cross-checking against this directory. D-ID's tradeoff, consistent with the whole avatar category, is that lip-sync and facial animation still read as synthetic on close inspection, particularly on longer scripts or non-frontal source photos — it's best suited to shorter, clearly-labeled synthetic content rather than anything trying to pass as unscripted human video.
Browse similar tools